Reference architectures
LLM observability and evaluation pipeline
Production traces feed online evals and a dataset; offline evals gate prompt changes.
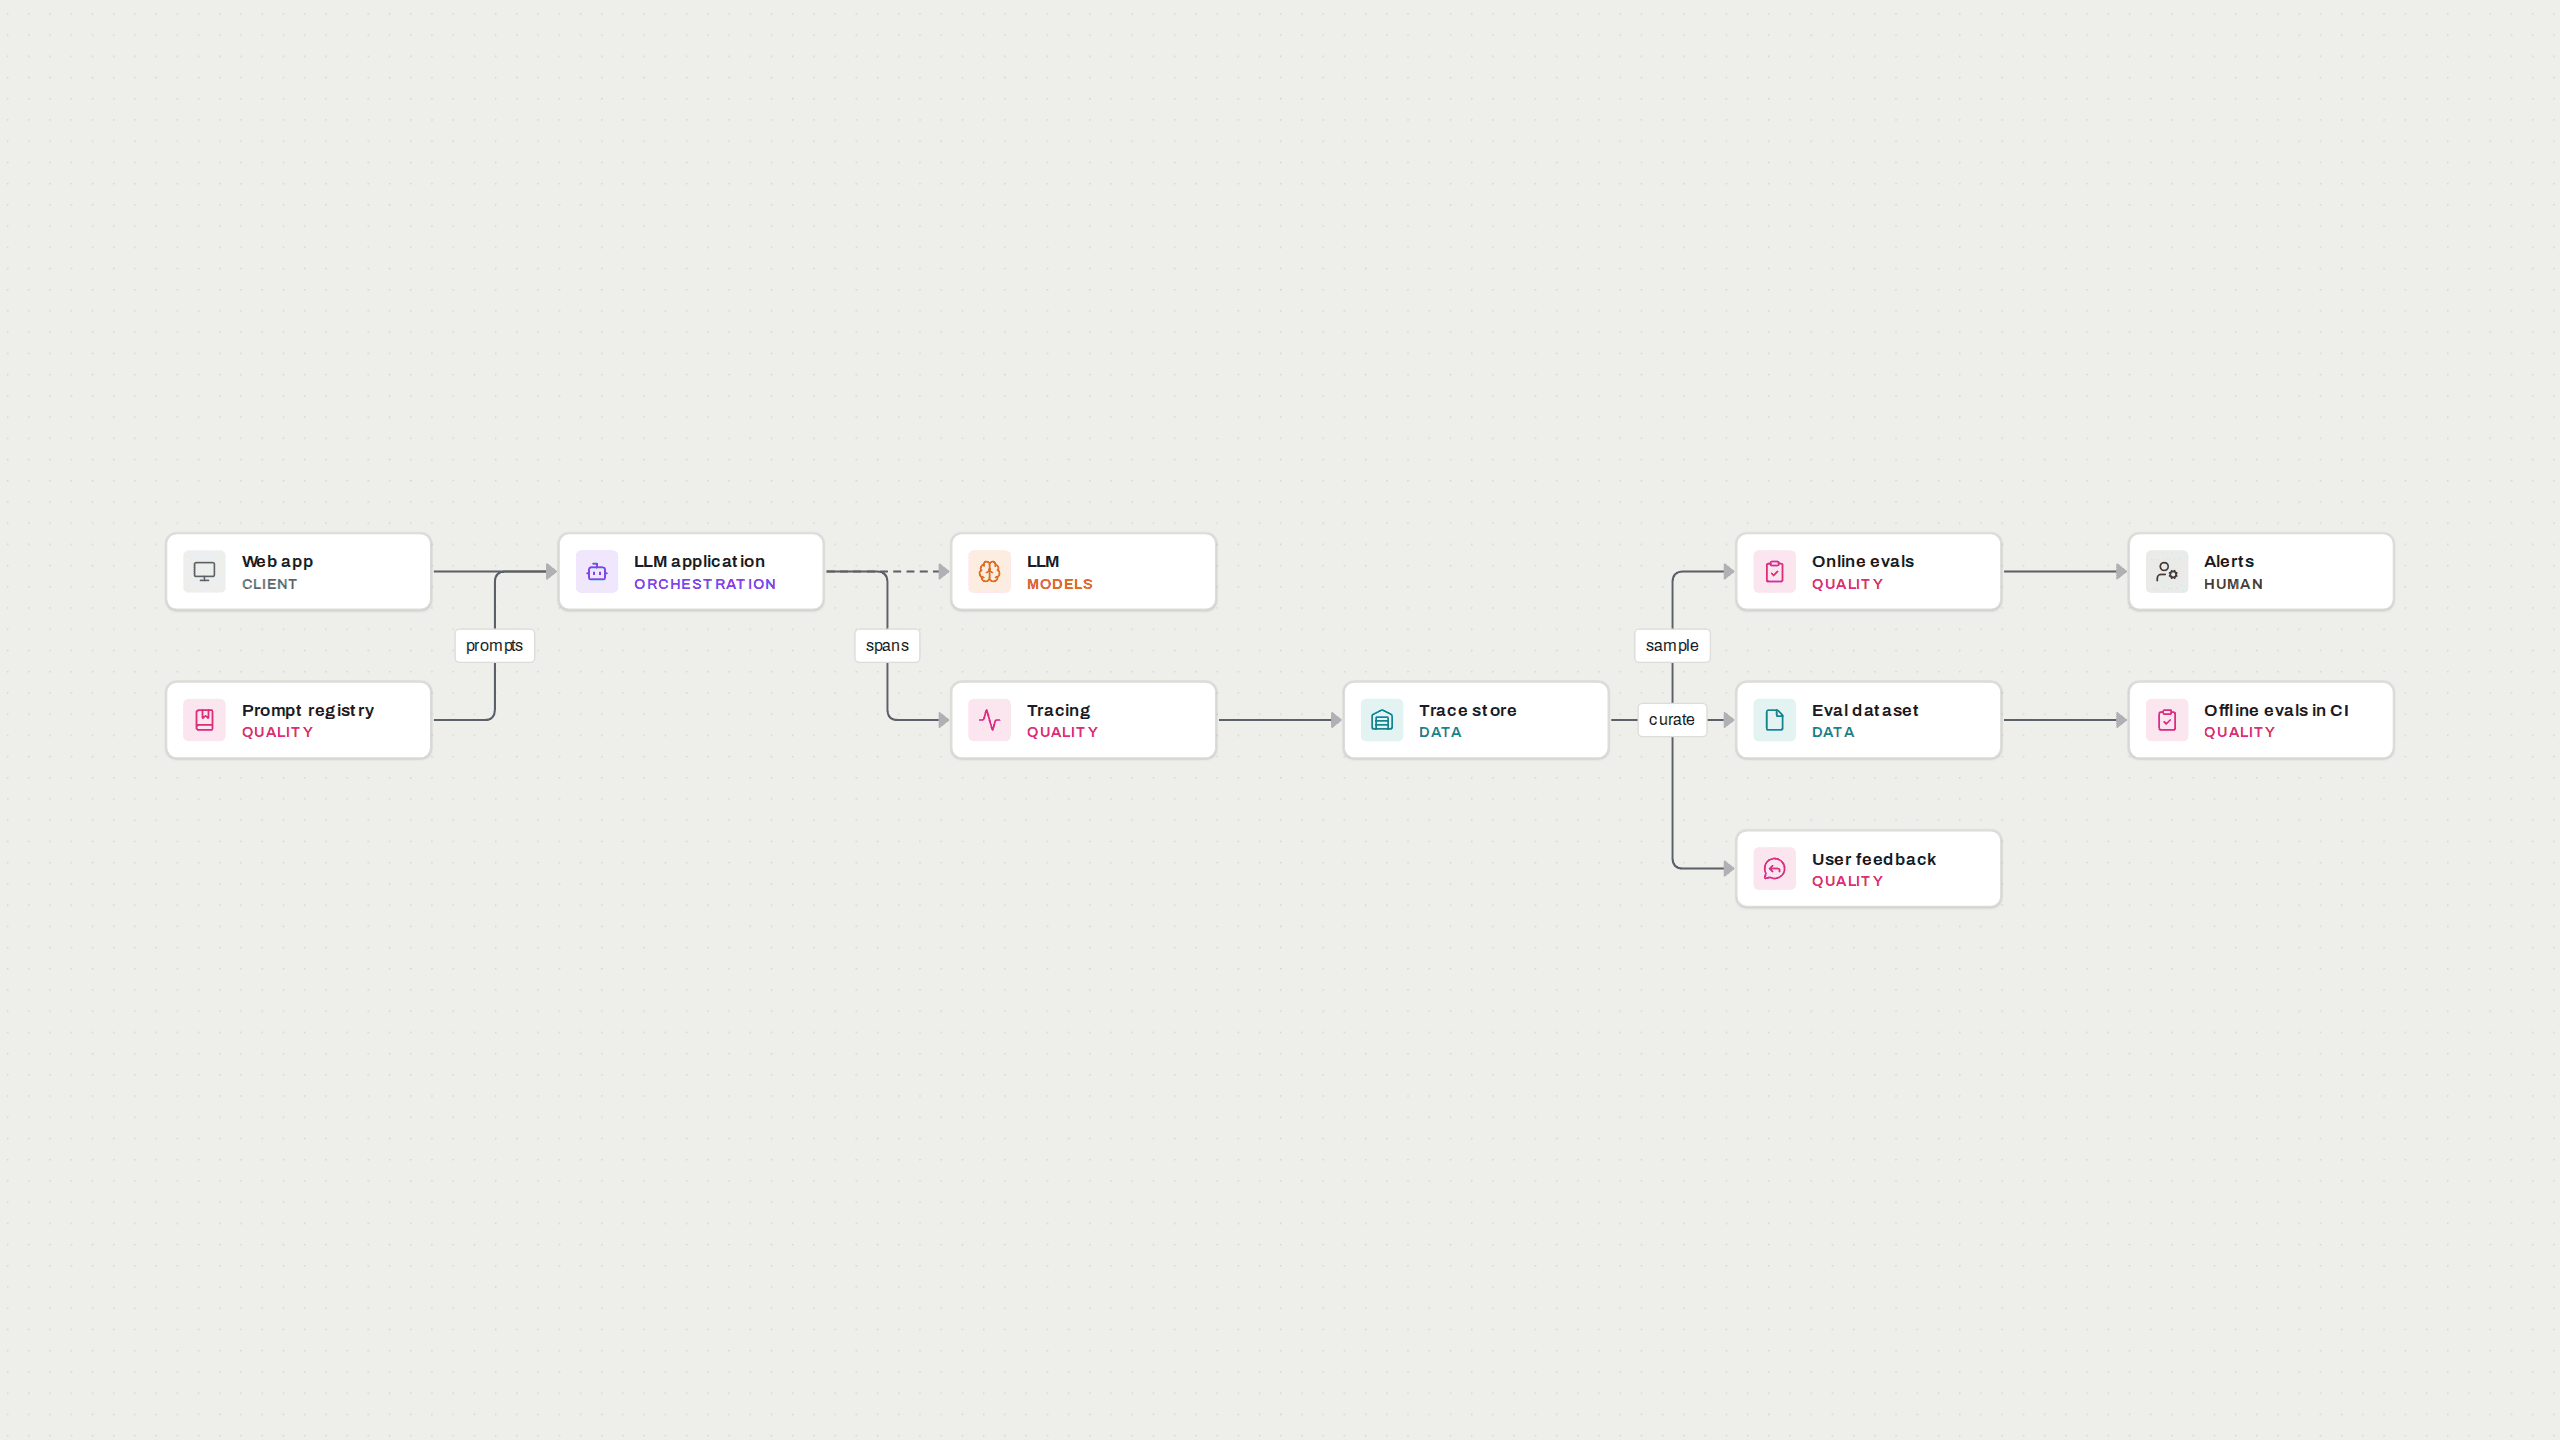
You cannot improve an LLM application you cannot see. This architecture records every model call as a trace and stores it. Online evals score a sample of live traffic and raise alerts. Interesting traces and user feedback are curated into an evaluation dataset. Offline evals run that dataset in CI whenever a prompt or model changes, so a regression is caught before release. Prompts live in a registry, not in the code.