Reference architectures
LLM gateway with model fallback
One gateway in front of every model: cache, routing, fallback and cost tracing.
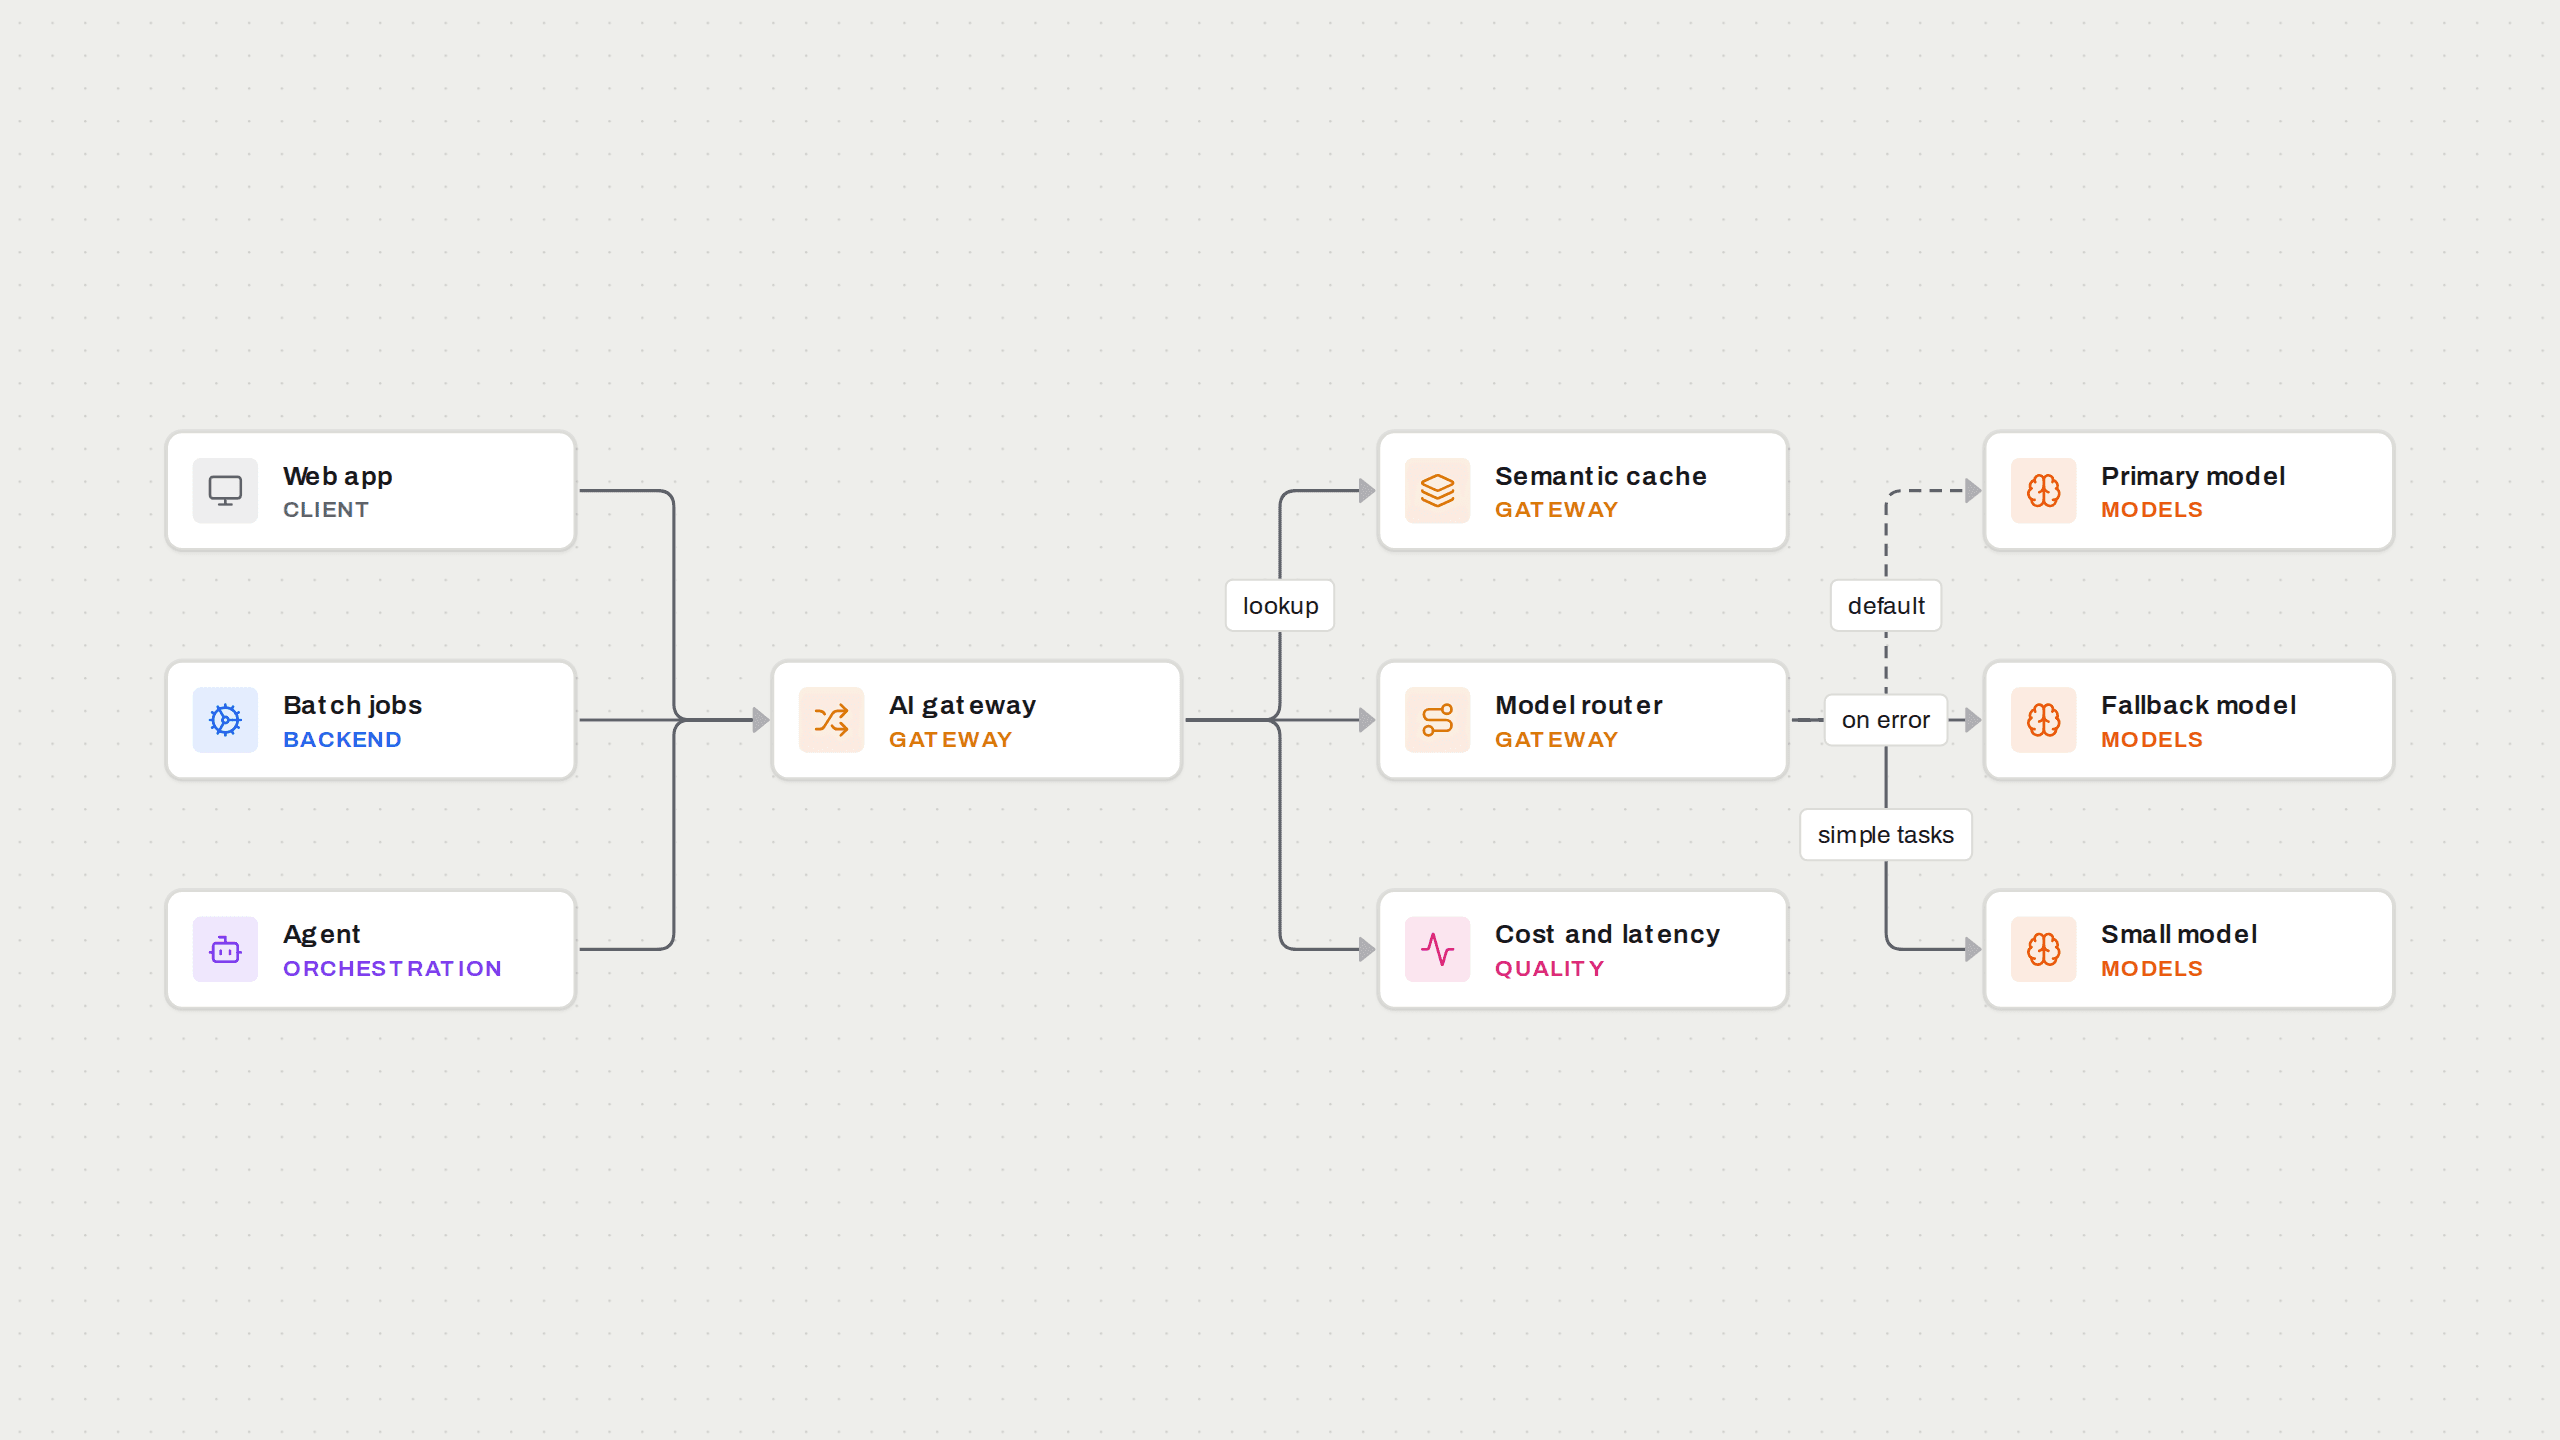
An LLM gateway is the single entry point for every model call in your company. Applications, batch jobs and agents send requests to the gateway instead of to a provider. The gateway answers repeated questions from a semantic cache, routes simple tasks to a small model, and falls back to a second model when the primary one fails or is rate limited. Because every call passes through it, cost and latency are traced in one place.